Demo · real software · synthetic patient
One referral, start to finish.
OpenAdapt enters a new patient into a test copy of OpenEMR, checks the saved chart, catches a save that didn't land and asks a person on their phone. Every picture here is from real software, and each one says what it is.
01
It enters the record
A person showed OpenAdapt this task once. Now it runs on its own: it types the referral's patient details (title, name, date of birth, sex, address, phone and email) and creates the chart. No AI model runs, and no screen leaves the computer.

This referral program: 41 steps
Press play to watch the run, or select any step on the program to see what it checks. A circle marks a step that confirms the patient first; the wide mark is the step that reads the saved chart back.
ProgramThis referral · 41 steps · 0 model calls
- LOOPFor each referralin the list
- 01–09Name9 steps · 3 fields
- 10–15Date of birth and sex6 steps · 2 fields
- 16–29Address14 steps · 4 fields
- 30–38Phone, email and country9 steps · 3 fields
- 39–41Create the chart3 steps · reads the chart back
- NEXTSaved and checkedon to the next referralSTOPChart not confirmeda person checks it
The test copy runs OpenEMR 8.0.0.3. The read-back of the 12 saved fields was done by our test setup.
02
It became a program the first time
The recording compiled into a program with a fixed set of steps. A program has as many steps as the task; this OpenEMR referral has 41. Each step knows how to find its field again, which ones confirm the right patient, and where to stop. The same steps run for every referral in the list. Select any step to see what it checks and jump the footage there.
- 41steps in this referral program, the same for every referral
- 12steps that confirm the right patient first
- 11checks of the saved chart after the save
- 14places it stops instead of guessing
Counted from the compiled program. Each step finds its field by the page's structure first, then by its picture, its text or nearby labels. Back to the program ↑
03
It catches a save that didn't land
A save can fail after everything on screen looks done. So after the save, OpenAdapt reads the record back from the system itself and compares it with what it typed.
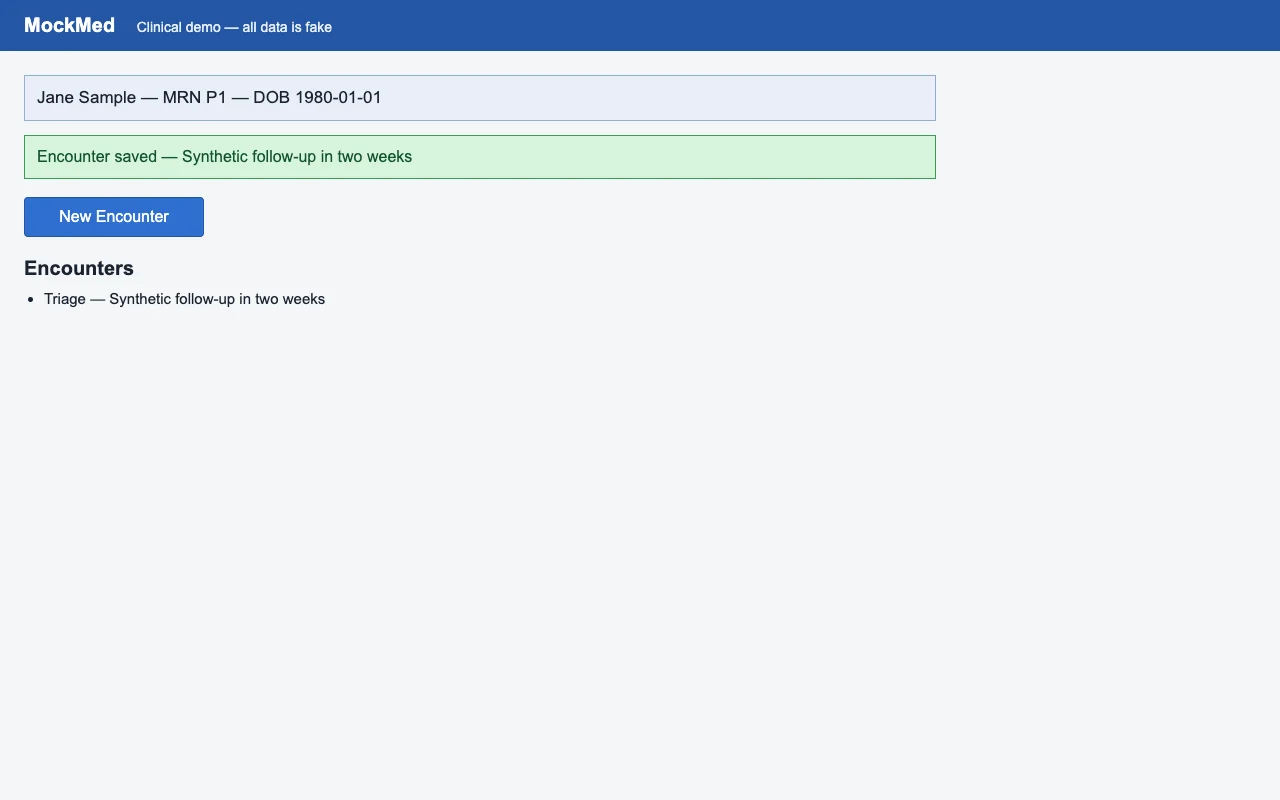
Done and checkedThe note was stored. The record check found 1 new note.
Stopped · Check the recordThe server rejected the note. The record check found 0 notes, so OpenAdapt stopped instead of reporting success, and won't retry until a person checks the record.
Both screens, right after the Save click. They are identical, byte for byte. Only the record check could tell them apart.
The command was openadapt quickstart --break-it (openadapt 1.17.0). The second run uses a server set to reject the write. The run's reports · Run it yourself ↓
It also stops before saving when
- The patient may already existWhen the EMR's duplicate check finds a similar chart, OpenAdapt stops before confirming and hands the referral to a person.How the stops work →
- The chart on screen is a look-alikeBefore typing into a chart, it confirms the patient. In our look-alike test set, it stopped on 5 of 5 look-alike patients.How the right-record check works →
04
A person answers on the phone
- By default, every save waits for a person.
- The card shows a picture of exactly what will be saved.
- Swipe right to save, or left to stop. There are 5 seconds to undo.
- A step that can't be undone needs a matching detail and a press-and-hold.
- Once a workflow has proved itself, you can have it ask only about problems.
Recorded 18 Oct 2026 from OpenAdapt Desktop's phone page. The connection to the computer is simulated for this recording; the picture on the card is a real frame from the referral run above. Showing each field's value on the card is in review.
05
Your agent alone, or with OpenAdapt
Alone, a computer-use agent decides every click, every time, from screenshots. With OpenAdapt, it does the task once and then calls the compiled program: the same path every time, no screenshots sent, $0 an entry, every save read back. Same test EMR, same synthetic referrals, timed from sign-in to the chart read back.
| Measure | Agent alone | With OpenAdapt |
|---|---|---|
| Model fees per referral | about $0.08 | $0 |
| Correct saves | 62 of 63 | 62 of 63 |
| Median time per referral | 36.5 s | 29.7 s |
Timed referral runs, 14 to 15 Oct 2026: a test copy of OpenEMR 8.0.0.3, 63 new-patient referrals each. The agent was Claude Sonnet 5.5 (claude-sonnet-5-5) at list price. Medians over the 62 correct runs each; the one miss in each arm saved nothing. OpenAdapt found each field by the page's structure; the same task replayed from a recording without it took 38.6 s, slower than the agent. How we measured
On screens with only pixels, such as remote desktop, the right-record check stops whenever the right patient's own record number has look-alike characters: 47 to 61 in 100 correct-patient checks on our test corpora (re-measured 17 Oct 2026). Extra stops, not wrong entries.
Being built now Not released
Not released yet. Each is an open pull request in the OpenAdapt repository; we list it here when it ships.
- Repair when the app changesAn agent proposes the fix and OpenAdapt tests it up to the save without saving; fixes that meet rules you set in advance go live without waiting.
- A program from a written requestDescribe the task; an agent does it once, and OpenAdapt keeps the run only if its saves check out.
- Saves through the app's own APIWhere the recording shows the app saving through an API, the program can call it directly instead of typing.
- Undo after a stopA record of exactly what a stopped run changed, with the steps to put it back.
- Patient details scrubbed by defaultBefore any recording or report leaves the computer.
- A guard for any agent's saveOne call that confirms the record, holds for approval and reads the save back, around a save your own agent makes.
Watch it catch a bad save on your computer
About a minute. It runs on synthetic data, needs no account, and nothing leaves your computer.
uvx --python 3.12 openadapt quickstart --break-itHow it works, in detail
A person, or an AI agent, does a task once. OpenAdapt turns that run into a program that makes the same entry every time with no AI model. Before it types, it confirms the right patient; after it saves, it reads the record back; when something doesn't match, it stops and asks a person.
A person or an agent shows the task
A staff member does the task once on a test patient or a test claim, while OpenAdapt records the screen and every click and keystroke. On this site, a test script stood in for that person.
A computer-use agent can show the task instead: OpenAdapt turns the agent's successful run into the same kind of program, so later entries make no model calls. A person accepts the program before it runs. Agent recording in web apps is released; in native Windows apps and over remote desktop it is on main and not yet released. How to set it up.
You can also give it several demonstrations. OpenAdapt compares them to find which values change, which steps repeat and which are optional. If they don't agree on what the task is, it says so and builds nothing. It can also fill a task's inputs from a referral PDF, a fax image or an email.
Who approves each entry
By default, every save waits for a person's approval, on the computer or on a paired phone. Look-ups that save nothing need none.
After a readiness test, if OpenAdapt can read saved records from your system's data, a workflow can ask a person only about problems. Repeated problems switch it back. A person can also sign a grant that lets a named system or agent answer saves; the result says who approved.
When something doesn't match, it stops and asks
There are two kinds of stop; the result says which.
It stops before saving
In our 2026-10-12 claims test, one claim had a mistyped insured number. openIMIS found no member, so the screen no longer matched the demonstration, and the program stopped before saving. No claim was written: Stopped before saving.
It stops after saving started
In our 2026-10-11 referral test, the referral said Rosa Delgado, born 1958-03-22. The EMR's duplicate check found a Rosa Delgado born 1958-03-27. The program stopped before confirming and flagged Check the record for a person. A separate read afterwards found no new chart.
What a stop doesn't do: the claims program stopped because openIMIS found no member, not because it compared the number with the document. If a mistyped number had belonged to another member, the screen would have looked normal, and only a record check or a person would catch it.
How every entry ends
Every entry ends with one plain result. It says "nothing was written" only when the run proves it.
| Result | What it means |
|---|---|
| Done and checked | Saved, then read back from the system's own data, and every field matched. |
| Stopped before saving | It stopped before changing anything and asked a person. Nothing was written, and the run proves it. |
| Check the record | It had started saving, so it can't promise nothing was stored. A person checks the record before anything is tried again. It never retries on its own. |
| Finished, not checked | It did the steps but didn't confirm the saved result. Practice runs and programs with no record check are always labeled this way. |
| Didn't finish | It couldn't complete the task. The result says what is known about whether anything was written. |
It reads the saved record back
After saving, OpenAdapt reads the record back another way, such as a report export, read-only API access or a database read, and compares the fields it typed. That catches a wrong field or record, a missed keystroke, or a step that ran too early. Re-reading the screen it typed on doesn't count: that shows what was typed, not what was stored. A run with no second way to read ends Finished, not checked, and we won't approve such a workflow to save entries on its own.
Why a separate read matters: in our fault test, 72 of 90 runs left the record wrong. A check of the screen's "Saved" message alone passed 54 of those 72. A read over the app's API missed 9; the full database read caught all 72. These were faults we injected on a test system: a coverage test, not a real-world error rate. More in How do you know an automation saved the record?.
It checks it's the right record
Before it types into a chart, it confirms the chart belongs to the right patient, and stops when it isn't sure. In our look-alike test set (same name, same birth date, record numbers like MG4408 and MG44O8), it stopped on 5 of 5 look-alike patients. More on the right-record check.
Its limits: the check covers the steps that carry a patient's identity. On pixel-only screens, such as remote desktop, it stops whenever the right patient's own record number has look-alike characters: 47 to 61 in 100 correct-patient checks on our test corpora (re-measured 17 Oct 2026). A confirmed list of the system's record numbers removes most of those stops. Extra stops, not wrong entries.
When the screen changes, it finds the field or stops
A recorded macro keeps clicking where a field used to be. OpenAdapt finds the field again by the page's structure, its label, its picture or nearby text, or stops. On Frappe Lending, after a cosmetic screen change, 3 of 3 runs found the fields again and were checked. Over remote desktop, 3 of 3 runs on a changed screen stopped. A fix ships as a new, tested version of the program, staged before it's used and possible to roll back.
Where it runs
It runs on a computer or virtual machine you control, signed in to your system. That computer keeps each run's full record. It works in web apps and, in early releases, native Windows and macOS apps and remote desktop. A real Citrix session isn't tested yet. Security and the data map.
What your IT team does, once
- Sets up one computer or virtual machine, signed in to the system.
- Installs the open-source engine with us and allows it to control the keyboard and mouse.
- Sets up the read-only access the record check needs. Some vendors charge for this or take weeks.
- Reviews where patient or member data goes.
What we've tested, and what we haven't
Every run below used synthetic records on open-source software or our own test apps. We have no partnership with any EMR or claims-system vendor, and we qualify each workflow on your own system before it touches a real record. All tested runs.
| System | Task | Result | Date |
|---|---|---|---|
| OpenEMR 8.0.0.3, open-source EMR, browser | Register a referred patient, timed against an AI agent | 62 of 63 saved correctly, same as the agent; 9 of 9 possible duplicates created no chart | Oct 2026 |
| MockMed, our synthetic clinic app | Add a note; then the same with the save rejected | Done and checked; with the save rejected, it stopped (Check the record) | Oct 2026 |
| openIMIS 25.10, open-source insurance system, browser | Enter a claim, 6 claims | 5 saved, 15 of 15 fields read back by our test setup; 1 stopped before saving | Oct 2026 |
| openIMIS 25.10, browser | Eligibility look-ups | 3 of 3 active confirmed; 3 of 3 expired stopped | Jul 2026 |
| Our scheduling app over real remote desktop | Book an appointment | 3 of 3 confirmed; 3 of 3 wrong-patient runs stopped | Jul 2026 |
| Frappe Lending, open source | Loan application after a screen change | 3 of 3 found the fields and were checked | Jul 2026 |
| Our own Windows test app | A form task | 3 of 3 confirmed by a database read | Jul 2026 |
Not tested yet
- A commercial EMR, claims system or policy system
- A real Citrix session
- A US payer portal or a carrier portal
- Phone approval on a real clinic's system
- Real patient or member data
Updated 2026-10-18.
Sources
- OpenAdapt quickstart with --break-it (openadapt launcher 1.17.0), MockMed synthetic clinic app, 18 Oct 2026 (the run's reports): the normal entry ended Done and checked by a read of the saved note; with the save rejected on purpose, the screen looked the same as the good save, and the run stopped and reported Check the record without retrying.
- Referral timing run, local OpenEMR 8.0.0.3 test copy, 14 to 15 Oct 2026 (run data): 8 synthetic referrals, OpenAdapt (a program compiled to find each field by the page's structure, 0 model calls) against Claude Sonnet 5.5 (claude-sonnet-5-5) as a computer-use agent in a capped harness, warm starts, interleaved blocks, each chart read back from the database. Blocks 2 to 10, normal referrals saved correctly: 62 runs each; median 29.7 s (OpenAdapt) and 36.5 s (agent); agent median $0.083 a run at list price. Both 62 of 63 normal referrals correct; on the possible duplicate, no new chart in 9 of 9 for both. Block 1 left out (CPU shared with another process); with it (blocks 1 to 10), 69 of 70 correct for both, 29.7 s and 37.6 s (n=69 each). The same task from the 10 Oct recording without the page's structure: 62 of 63, 38.6 s median, slower than the agent.
- OpenAdapt on OpenEMR 8.0.0.3 (open-source EMR), local test copy, 11 Oct 2026. One program ran over 8 synthetic eReferrals in one batch, with 0 AI model calls. 7 new patients were saved; our test setup read each chart back through the OpenEMR API and database, and 12 of 12 fields matched the referral. The 8th (Rosa Delgado, same name as an existing chart, different birth date) stopped at the EMR's duplicate check; afterwards no new chart existed. The engine labels the saved runs "Finished, not checked" (practice profile) and the stop "Check the record".
- OpenAdapt on openIMIS 25.10 (open-source insurance system), local test copy, 12 Oct 2026. A program learned from one demonstration entered 6 synthetic health-facility claims in one batch, with 0 AI model calls. 5 were saved; our test setup read each back through SQL and the openIMIS API, and 15 of 15 fields matched the claim document. On the 6th, the insured number had two digits swapped: openIMIS found no member, the screen no longer matched the demonstration, and the program stopped before saving (no claim was written). The engine labels the 5 saved runs "Finished, not checked", because this program has no record check of its own yet.
- OpenAdapt on openIMIS 25.10 (open-source insurance system, not a US payer portal), July 2026, synthetic members: 3 of 3 active policies confirmed, 3 of 3 expired policies stopped, 0 active policies stopped by mistake. Checked by a read-only database query of the policy, product and dates.
- OpenAdapt remote-desktop test, 30 Jul 2026: a fictional clinic scheduling app over a real remote-desktop connection (FreeRDP, not Citrix), synthetic patients. 3 of 3 bookings confirmed by a read-only database query; 3 of 3 wrong-patient runs stopped with 0 rows written; 3 of 3 runs on a changed screen stopped. 0 AI model calls.
- OpenAdapt look-alike test set (synthetic rows), 2026: 5 of 5 look-alike patients stopped; of the 2 control cases, the right patient was let through and a plainly different patient was stopped. On pixel-only screens the check stops whenever the right patient's own record number has look-alike characters (O and 0, l and 1); on our test corpora that was 47 to 61 in 100 correct-patient checks, re-measured 17 Oct 2026 (IDENTITY_EVIDENCE.md). With a confirmed list of the system's record numbers (openadapt-flow 2.2.0), those stops on a rendered record list fell from 176 to 3 in 280 clicks whose neighboring row wasn't a look-alike twin (KNOWN_IDS.md).
- OpenAdapt on Frappe Lending 16.2.0 (open source), 16 Jul 2026, synthetic applicants: 6 of 6 loan applications checked through the API, a database read and a table-change audit (3 normal runs, 3 after a cosmetic screen change); 5 of 5 injected faults stopped before saving.
- OpenAdapt on our own Windows test app (UI Automation), 17 Jul 2026: 3 of 3 runs with saves confirmed by a database read; missing and ambiguous targets refused 3 of 3.
- OpenAdapt fault test, openadapt-flow benchmark/effect_e2e, 2026: faults injected into our own engine on a test record system, 90 runs; 72 left the record wrong. A check of the screen alone passed 54 of those 72; a read-back over the app's REST API passed 9 of them; the full database read caught all 72. A coverage test over a fixed fault list, not a real-world error rate.